2026

UniVVT: A Unified End-to-End Framework for High-Fidelity Video Virtual Try-on

Yushe Cao, Shikun Feng, Fei Shen, Dianxi Shi, Jianqiang Xia, Chun Yu, Junliang Xing

Association for the Advancement of Artificial Intelligence(AAAI,UnderReview) 2027

Video Virtual Try-On (VVT) synthesizes a video of a person wearing a target garment while preserving identity, motion, and scene dynamics. Dominant approaches cast VVT as mask-conditioned video inpainting and rely on separate modules for human parsing, pose estimation, and…
UniVVT: A Unified End-to-End Framework for High-Fidelity Video Virtual Try-on

Yushe Cao, Shikun Feng, Fei Shen, Dianxi Shi, Jianqiang Xia, Chun Yu, Junliang Xing

Association for the Advancement of Artificial Intelligence(AAAI,UnderReview) 2027

Video Virtual Try-On (VVT) synthesizes a video of a person wearing a target garment while preserving identity, motion, and scene dynamics. Dominant approaches cast VVT as mask-conditioned video inpainting and rely on separate modules for human parsing, pose estimation, and…

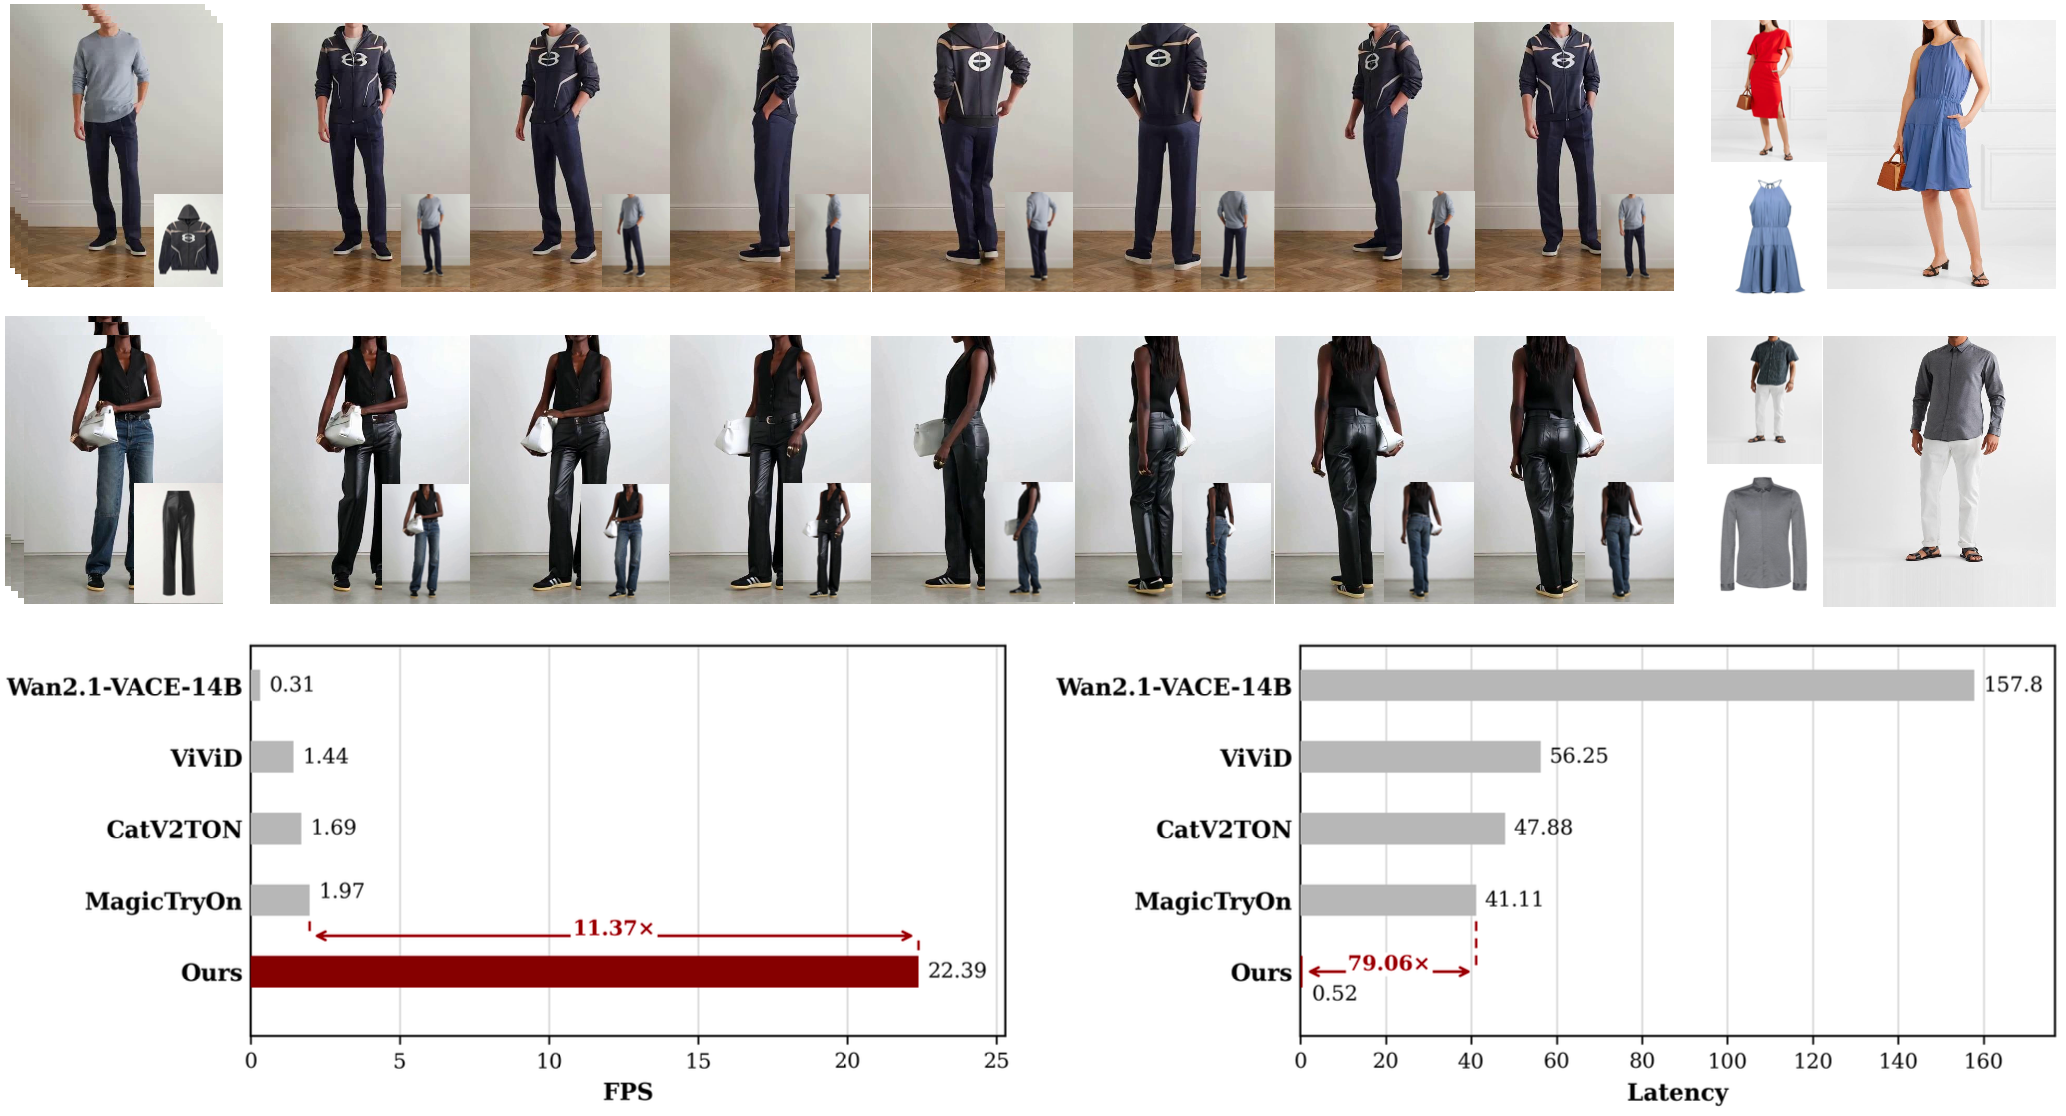
LiveVVT: High-Fidelity Video Virtual Try-On in Real Time

Yushe Cao, Shikun Feng, Ruxiang Duan, Liyong Wang, Dianxi Shi, Chun Yu, Junliang Xing

Association for the Advancement of Artificial Intelligence(AAAI,UnderReview) 2027

Diffusion-based Video Virtual Try-On (VVT) achieves high visual fidelity through bidirectional spatio-temporal modeling, but complete-clip dependence incurs prohibitive latency and computational overhead in practical continuous deployment. Naively enforcing causality disrupts pretrained bidirectional priors and substantially degrades synthesis quality. We introduce…
LiveVVT: High-Fidelity Video Virtual Try-On in Real Time

Yushe Cao, Shikun Feng, Ruxiang Duan, Liyong Wang, Dianxi Shi, Chun Yu, Junliang Xing

Association for the Advancement of Artificial Intelligence(AAAI,UnderReview) 2027

Diffusion-based Video Virtual Try-On (VVT) achieves high visual fidelity through bidirectional spatio-temporal modeling, but complete-clip dependence incurs prohibitive latency and computational overhead in practical continuous deployment. Naively enforcing causality disrupts pretrained bidirectional priors and substantially degrades synthesis quality. We introduce…

Long-Tail Adaptive Flow Matching with Explicit Conditional Consistency Guidance for Precise Multimodal Face Synthesis

Yushe Cao, Xuechao Zou, Dianxi Shi, Junliang Xing, Chun Yu, Yuanze Wang

IEEE Transactions on Multimedia 2026

Although diffusion-based methods have substantially improved the controllability of multimodal face synthesis, their semantic alignment remains suboptimal because most existing approaches rely on implicit latent-space objectives to model the relationship between denoising variables and multimodal conditions. Such implicit modeling is…

Long-Tail Adaptive Flow Matching with Explicit Conditional Consistency Guidance for Precise Multimodal Face Synthesis

Yushe Cao, Xuechao Zou, Dianxi Shi, Junliang Xing, Chun Yu, Yuanze Wang

IEEE Transactions on Multimedia 2026

Although diffusion-based methods have substantially improved the controllability of multimodal face synthesis, their semantic alignment remains suboptimal because most existing approaches rely on implicit latent-space objectives to model the relationship between denoising variables and multimodal conditions. Such implicit modeling is…

2025
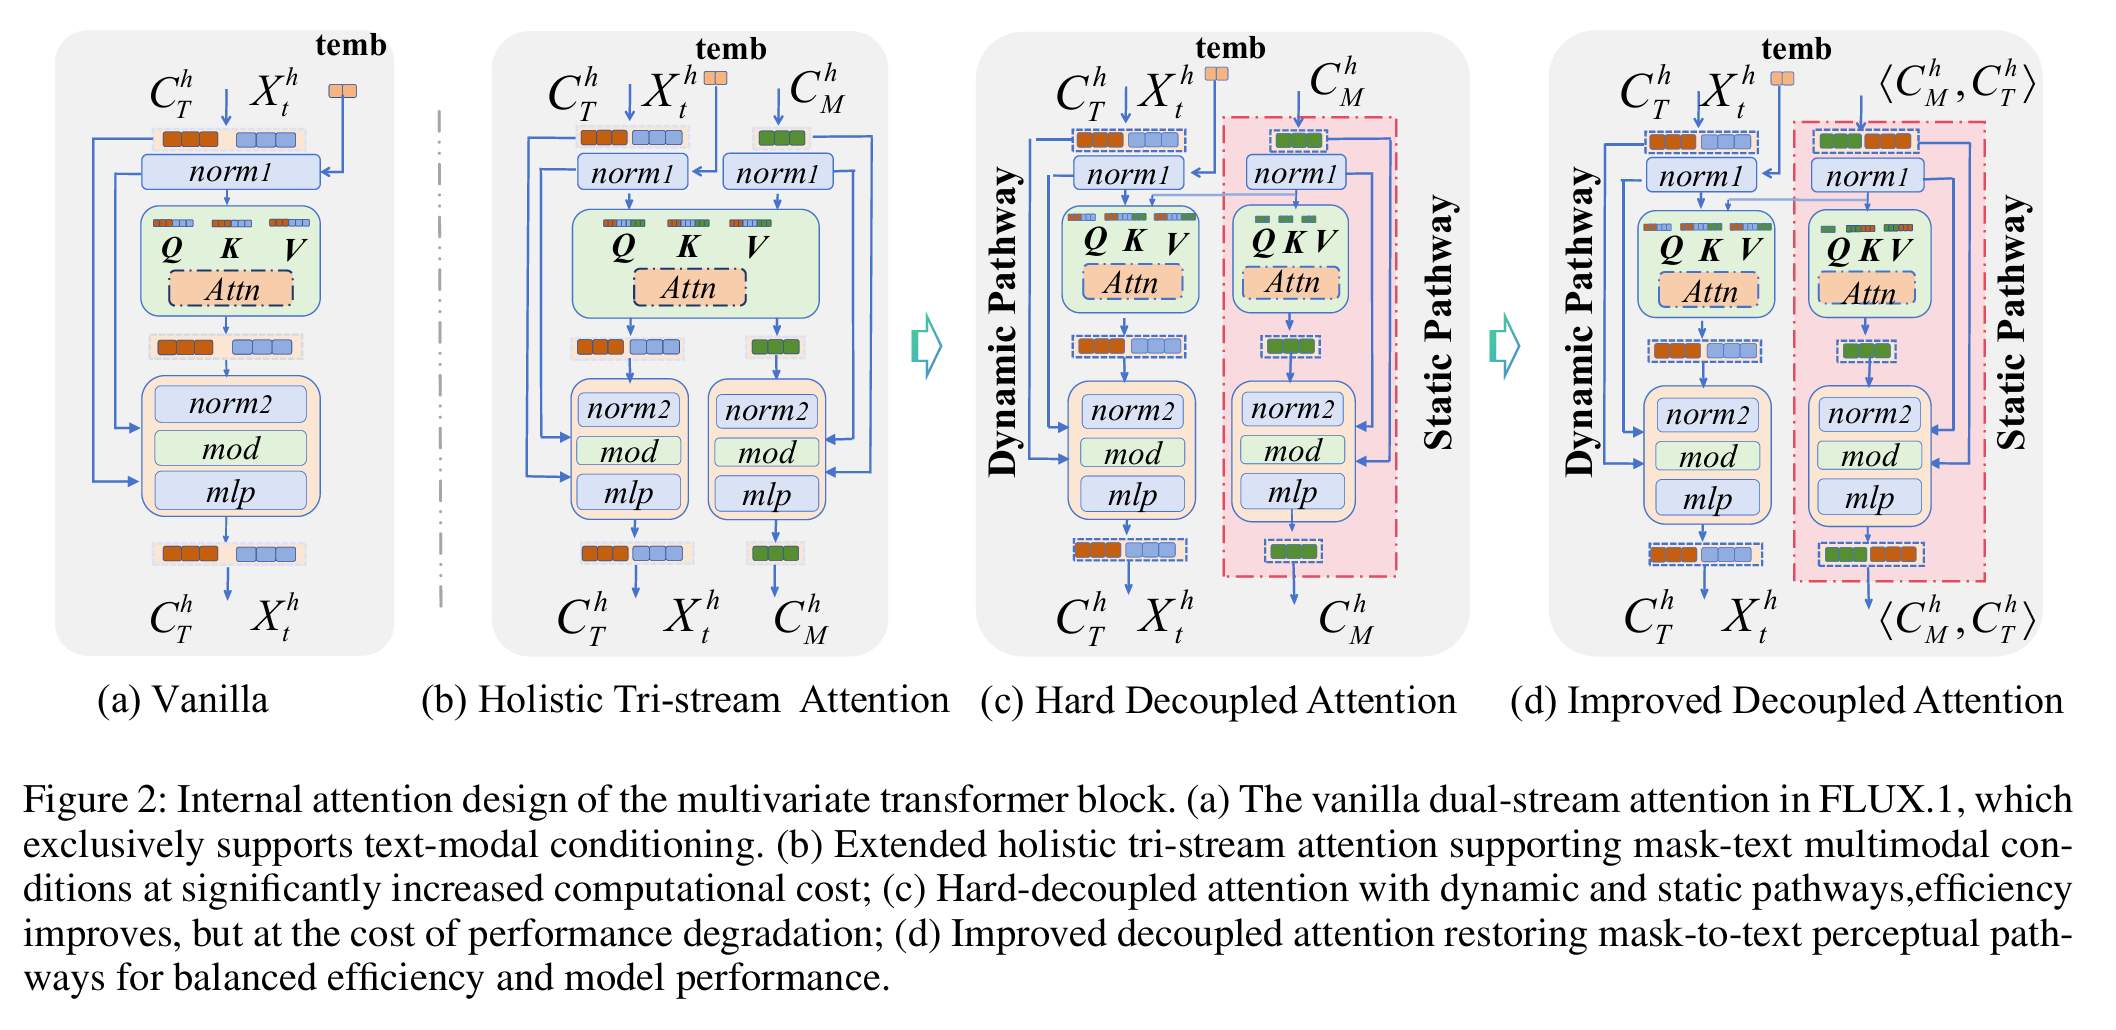
Multivariate Diffusion Transformer with Decoupled Attention for High-Fidelity Mask-Text Collaborative Facial Generation

Yushe Cao, Dianxi Shi, Xing Fu, Xuechao Zou, Haikuo Peng, Xueqi Li, Chun Yu, Junliang Xing

Association for the Advancement of Artificial Intelligence 2026

While significant progress has been achieved in multimodal facial generation using semantic masks and textual descrip tions, conventional feature fusion approaches often fail to enable effective cross-modal interactions, thereby leading to suboptimal generation outcomes. To address this chal lenge, we…

Multivariate Diffusion Transformer with Decoupled Attention for High-Fidelity Mask-Text Collaborative Facial Generation

Yushe Cao, Dianxi Shi, Xing Fu, Xuechao Zou, Haikuo Peng, Xueqi Li, Chun Yu, Junliang Xing

Association for the Advancement of Artificial Intelligence 2026

While significant progress has been achieved in multimodal facial generation using semantic masks and textual descrip tions, conventional feature fusion approaches often fail to enable effective cross-modal interactions, thereby leading to suboptimal generation outcomes. To address this chal lenge, we…

2024
Convallis a cras semper auctor neque vitae rutrum quisque non tellus orci ac

Your Name, James Wang, Some Other Name, John Doe

International Conference on Machine Learning (ICML) 2024 Spotlight

Photo by Pineapple Supply Co. on Unsplash. Please put a tldr (too-long-didnt-read, 1~2 sentences) of your publication here. It is not recommended to put the actual abstract here because it is usually too long to fit in. $\LaTeX$ is supported.…

Convallis a cras semper auctor neque vitae rutrum quisque non tellus orci ac

Your Name, James Wang, Some Other Name, John Doe

International Conference on Machine Learning (ICML) 2024 Spotlight

Photo by Pineapple Supply Co. on Unsplash. Please put a tldr (too-long-didnt-read, 1~2 sentences) of your publication here. It is not recommended to put the actual abstract here because it is usually too long to fit in. $\LaTeX$ is supported.…